
Text Extraction
Invoice totals, contract clauses and order numbers often reach an application only as PDF files. To process them, your code needs the text: all of it for a search index or a language model, or single values at a known place. TX Text Control reads the text lines of a PDF together with their page and position. You get the text page by page, search it with regular expressions, read values from an area of the page and return the lines to a web client.
Loading a PDF with PDFImportSettings.GenerateLines to get its plain text, and a first search with Lines.Find, are shown in Read the Text in Getting Started. Converting a PDF into an editable document is the subject of PDF Conversion.
How Text Extraction Works
A PDF file describes what each character looks like and where it's placed on the page, but not necessarily which character it is. Most PDF files contain a character mapping that makes the text readable, and TX Text Control extracts all text it can identify, adds missing spaces and puts text blocks into their logical order. It imports PDF documents that were created digitally; a scanned page is an image, and its text has to be recognized with OCR before it can be extracted.
Two ways lead to the text:
| Way | Returns | Use it for |
|---|---|---|
ServerTextControl.Load with PDFImportSettings GenerateLines, then ServerTextControl.Text | The text of the document as one string, without images and paragraph formatting | Search indexes, language models, full-text comparisons |
The Lines class of the TXTextControl.DocumentServer.PDF.Contents namespace | Each text line with its page number and position | Text per page, searches, values at a position |
Lines reads all text lines of a PDF file or byte array when it's created, without a ServerTextControl instance in your code. ContentLines returns them as a list of ContentLine objects, and every call of Find filters them. Create a Lines object once per document and call Find as often as you need.
A ContentLine has these properties:
| Property | Contains |
|---|---|
| Page | The number of the page that contains the line |
| Text | The text of the line |
| X, Y, Width, Height | The position and size of the line on its page, in points |
| Rectangle | The bounds of the line as a RectangleF |
A password-protected PDF can't be read without its password; Loading Documents shows how to load it with LoadSettings.UserPassword.
Read the Text Page by Page
When a summary, a search result or a prompt for a language model refers to a single page, it needs the text of that page. The following program groups the lines of a PDF by page and prints the text of each page in reading order:
using TXTextControl.DocumentServer.PDF.Contents;

Lines lines = new Lines("Documents/input.pdf");

var pages = lines.ContentLines
    .GroupBy(line => line.Page)
    .OrderBy(group => group.Key);

foreach (var page in pages)
{
    Console.WriteLine($"--- Page {page.Key} ---");

    // From top to bottom, then from left to right
    foreach (ContentLine line in page.OrderBy(line => line.Y).ThenBy(line => line.X))
    {
        Console.WriteLine(line.Text);
    }
}
The program sorts the lines by their Y and X coordinates, as the blog article Mining PDFs with Regex in C#: Practical Patterns, Tips, and Ideas does. Lines takes the path of a PDF file or the PDF as a byte array.
Search With Regular Expressions
Find with a regular expression returns every line that contains a match. The following program finds invoice numbers and amounts in a PDF and counts the matches per page:
using System.Text.RegularExpressions;
using TXTextControl.DocumentServer.PDF.Contents;

Lines lines = new Lines("Documents/input.pdf");

// Invoice numbers such as INV-2025-001
List<ContentLine> invoiceNumbers = lines.Find(@"\bINV-\d{4}-\d{3}\b", RegexOptions.IgnoreCase);

foreach (ContentLine line in invoiceNumbers)
{
    Match match = Regex.Match(line.Text, @"\bINV-\d{4}-\d{3}\b", RegexOptions.IgnoreCase);
    Console.WriteLine($"Page {line.Page}: {match.Value}");
}

// Amounts such as $199.99 or $1,299.00
List<ContentLine> amounts = lines.Find(@"\$\s?\d{1,3}(,\d{3})*(\.\d{2})?", RegexOptions.None);

foreach (var page in amounts.GroupBy(line => line.Page))
{
    Console.WriteLine($"Page {page.Key}: {page.Count()} lines with amounts");
}
The code works as follows:
Find(string regex, RegexOptions options)takes a .NET regular expression and its options and returns the lines in which the expression matches.Findreturns whole lines, soRegex.Matchextracts the matched value from the text of each line.Find(string text)without options returns the lines that contain the text.
A value that wraps to the next line isn't found by a single-line expression. The blog article of the previous section shows patterns for clause numbers, dates and party names and reads the lines before and after a match for context.
Read a Value From an Area of the Page
Documents of the same kind, such as invoices from one supplier or completed forms, print their values at the same place. Find with a rectangle returns the lines in that area. The following program finds the area of the invoice number in a sample invoice and reads the same area of all invoices in a folder:
using System.Drawing;
using TXTextControl.DocumentServer.PDF.Contents;

// Find the area of a known value in a sample document
Lines sample = new Lines("Documents/invoice-sample.pdf");
ContentLine? known = sample.Find("INV-2025-001").FirstOrDefault(line => line.Page == 1);

if (known == null)
{
    Console.WriteLine("The sample invoice doesn't contain the invoice number.");
    return;
}

RectangleF area = known.Rectangle;

// Read the same area of other documents of the same layout
foreach (string file in Directory.GetFiles("Documents/Invoices", "*.pdf"))
{
    Lines lines = new Lines(file);

    // true: lines that intersect the area, not only lines completely inside it
    ContentLine? value = lines.Find(area, true).FirstOrDefault(line => line.Page == 1);

    Console.WriteLine($"{Path.GetFileName(file)}: {value?.Text ?? "(no value)"}");
}
The code works as follows:
Find(RectangleF rectangle, bool partially)returns the lines in a rectangle. Withfalse, a line must lie completely inside the rectangle; withtrue, it's enough that the line intersects it, so a longer value is still found.- The rectangle comes from a line the program found, so it uses the coordinates of the PDF documents themselves instead of hard-coded values.
Find(PointF position, float radius, bool partially)returns the lines within a radius around a point.
The blog article Template-Based Text Extraction from PDF Documents in .NET C# extracts several fields of flattened forms this way.
Get the Text and the Coordinates in One Load
When your code needs both the text and the positions of a PDF, one Load call provides them. With LoadEmbeddedData in the import settings, LoadSettings.EmbeddedData contains the text coordinates as an XML string, in which each line has its page number and position:
using TXTextControl;

using (ServerTextControl tx = new ServerTextControl())
{
    tx.Create();

    LoadSettings loadSettings = new LoadSettings()
    {
        PDFImportSettings = PDFImportSettings.GenerateLines | PDFImportSettings.LoadEmbeddedData
    };

    tx.Load("Documents/input.pdf", StreamType.AdobePDF, loadSettings);

    Console.WriteLine(tx.Text);

    if (loadSettings.EmbeddedData != null &&
        loadSettings.EmbeddedData.TryGetValue(EmbeddedDataFormat.TextCoordinates, out object? coordinates))
    {
        File.WriteAllText("coordinates.xml", coordinates.ToString());
    }
}
The keys of the dictionary are values of EmbeddedDataFormat: TextCoordinates, FormFields and MetaData. The dictionary is filled only when LoadEmbeddedData is set and contains the formats the PDF provides.
Return the Lines of an Upload From ASP.NET Core
A web client, for example a viewer that highlights search results, can receive the lines of a PDF as JSON. The following action reads the lines of an uploaded PDF and returns them:
using Microsoft.AspNetCore.Mvc;
using TXTextControl.DocumentServer.PDF.Contents;
public class PdfTextController : Controller
{
[]
public IActionResult GetLines(IFormFile document)
{
// Copy the upload into a byte array
byte[] data;
using (MemoryStream memoryStream = new MemoryStream())
{
document.CopyTo(memoryStream);
data = memoryStream.ToArray();
}
Lines lines = new Lines(data);
// Page, text, position and size of each line
return Json(lines.ContentLines);
}
}
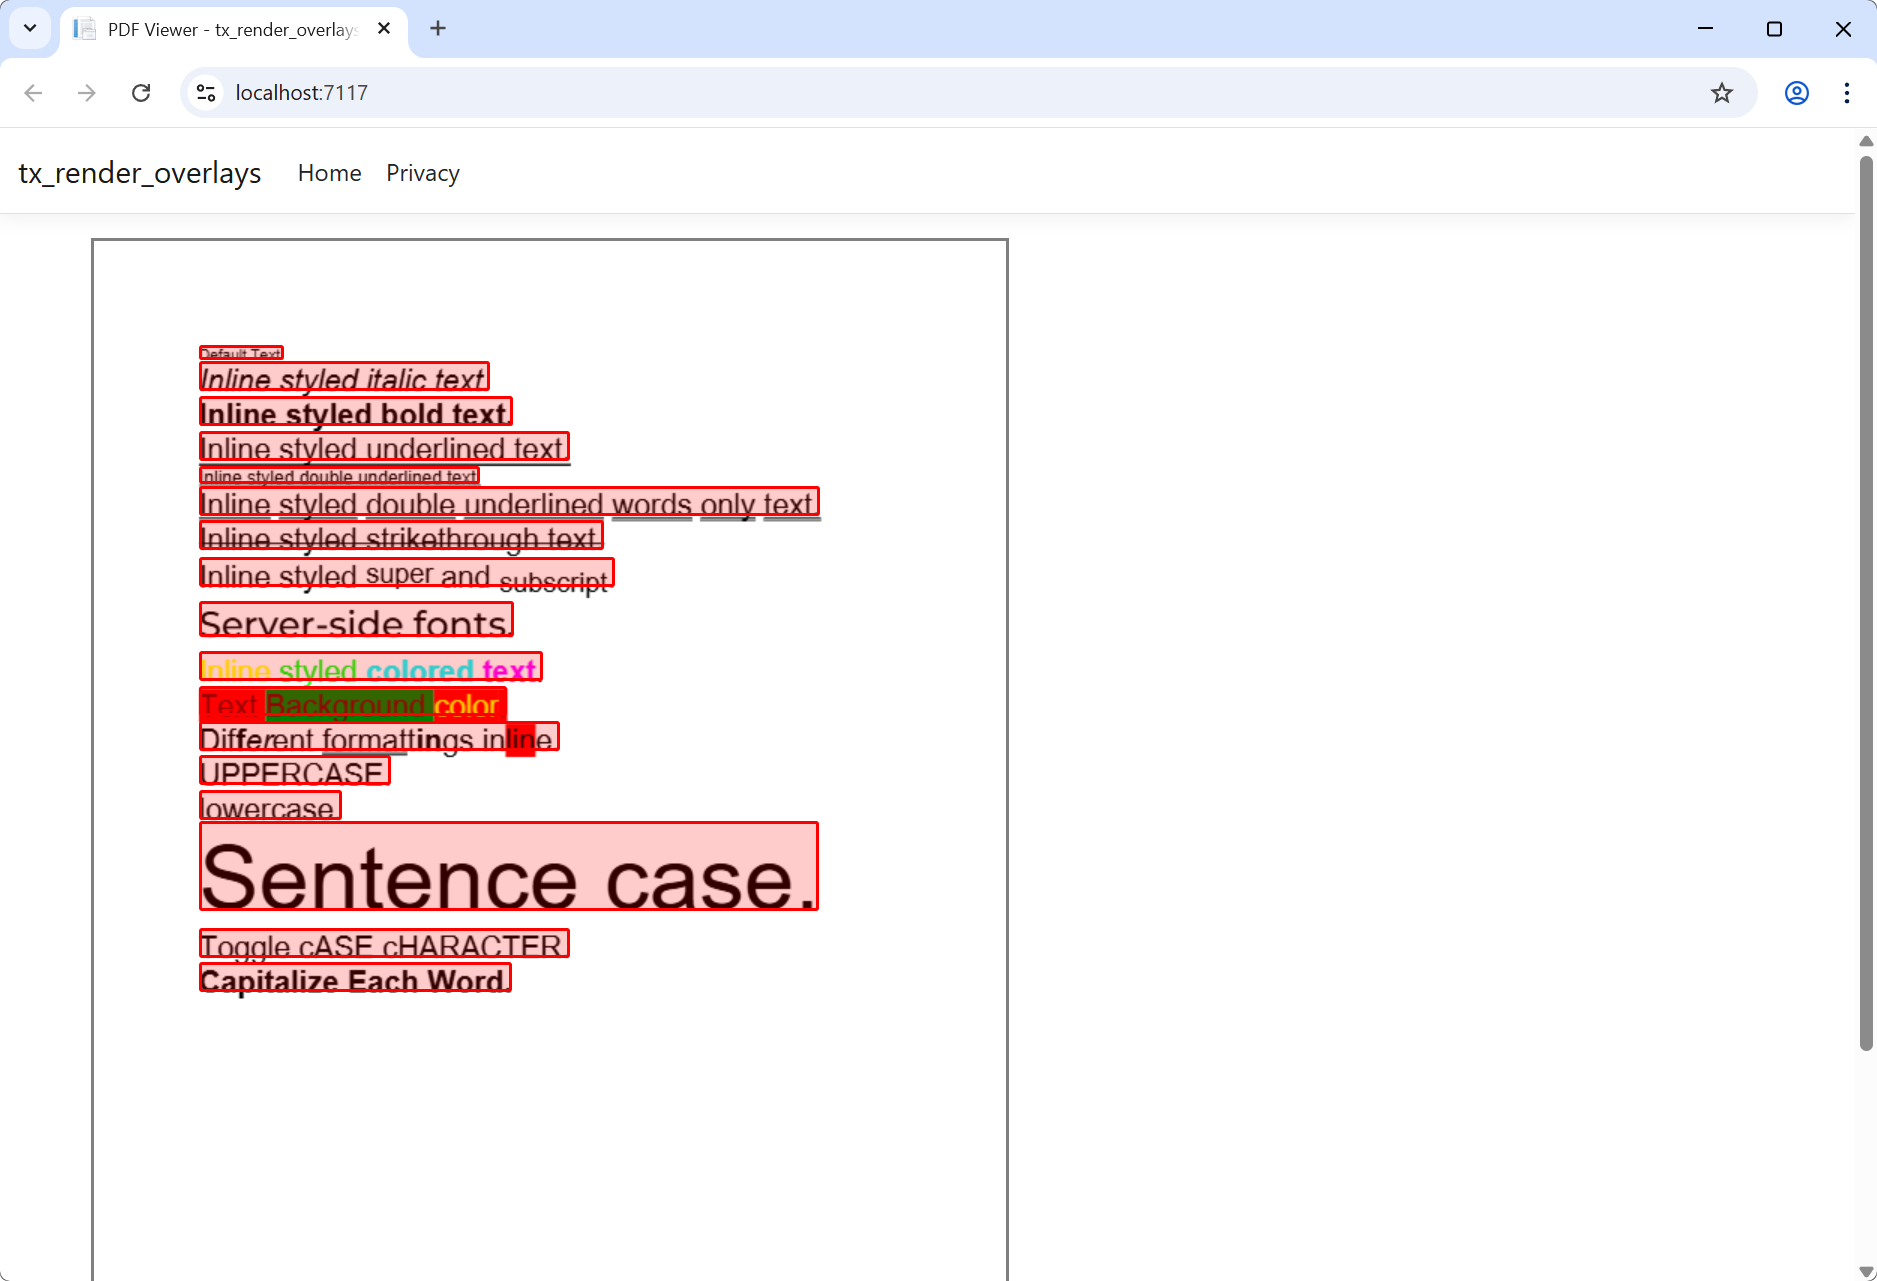
The blog article Visualizing Extracted PDF Content in a PDF.js Viewer Using TX Text Control in C# ASP.NET Core draws the returned lines over the pages in a browser.
Each rectangle marks the bounds of one ContentLine, converted into the coordinates of the PDF.js viewer:
Use Extracted Text With AI
Extracted text is the input of many AI workflows: classifying documents, answering questions about their content or indexing them for retrieval. The blog articles PDF Document Classification with OpenAI and TX Text Control in C# and Chat PDF - A Generative AI Application for PDF Documents using TX Text Control and OpenAI Functions in C# send the text of PDF documents to a language model. AI Integration describes these scenarios, including RAG and Document Analysis.
Next Steps
- PDF Conversion: convert PDF documents into editable formats.
- PDF Forms: read the values of form fields.
- Document Metadata: read the title, author and keywords of a PDF.
- Attachments: extract the files embedded in a PDF.